
GLM-Image
GLM-Image é uma ferramenta de inteligência artificial de ponta projetada para otimizar tarefas de Image Generators.
Categorias Relacionadas
Leituras Relevantes
Ferramentas de IA Relacionadas

AI Clothes Swap
AI Clothes Swap is a free AI clothes changer and virtual try-on studio for stylists, e-commerce, and social creators.

Wondershare Relumi
AI photo editor for iOS/Android, fixing blinks, restoring old photos, animating portraits, and enhancing images with text-to-edit features.
FLUX 3
FLUX 3 is a multimodal foundation model for video, image, and audio generation, offering action prediction and real-world visual intelligence.
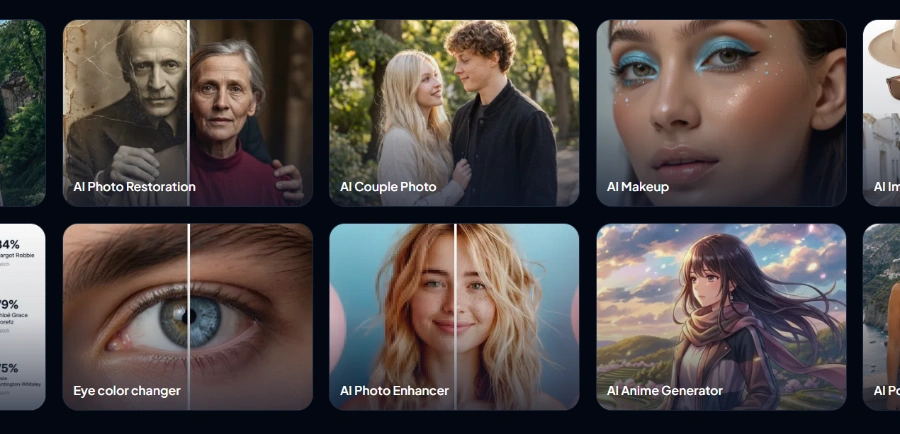
iLikeIMG
iLikeIMG offers 90+ free AI tools online for photo and video editing, enhancement, and generation without installation.
ImageGenerator IO
ImageGenerator IO is a free AI image generator that creates stunning visuals from text prompts and reference images for various creative projects.
Senzia
Senzia is a free online AI video, image, and audio generator that transforms ideas, text, photos, or audio into cinema-grade visuals without editing skills.
Qwen3.8-Max
Qwen is a family of generalist AI models, including LLMs and multimodal capabilities, developed by the Qwen Team.
Beatmo
Beatmo is an AI tool that transforms still photos into dynamic motion videos, offering photo animation, text-to-visual generation, and image reshaping for creators.
GLM-Image utilizes a unique model architecture that combines a 9B-parameter autoregressive generator, initialized from GLM-4-9B-0414 and expanded with visual tokens, with a 7B-parameter diffusion decoder based on a single-stream DiT architecture for latent-space image decoding.
The diffusion decoder is equipped with a Glyph Encoder text module, which significantly improves the accuracy and quality of text rendering within generated images, making it suitable for information-dense visual content.
The model incorporates a post-training phase using a fine-grained, modular feedback strategy based on the GRPO algorithm. This approach substantially enhances both semantic understanding and visual detail quality, with separate feedback for aesthetics/semantic alignment (autoregressive module) and detail fidelity/text accuracy (decoder module).
GLM-Image can generate high-detail images from textual descriptions, demonstrating particularly strong performance in scenarios that involve information-dense or knowledge-intensive prompts.
The model supports a wide array of image-to-image tasks within a single framework, including image editing, style transfer, identity-preserving generation for people and objects, and maintaining multi-subject consistency.
GLM-Image is fully integrated with the Hugging Face `transformers` and `diffusers` libraries, allowing for easy installation and usage via standard Python pipelines for both text-to-image and image-to-image tasks.
Informações Detalhadas de Preços
- Exceptional text-rendering capabilities within generated images due to the Glyph Encoder.
- Strong performance in knowledge-intensive generation scenarios, requiring precise semantic understanding.
- Maintains high-fidelity and fine-grained detail generation.
- Supports a comprehensive range of image-to-image tasks, including editing, style transfer, and identity preservation.
- Utilizes a decoupled reinforcement learning approach (GRPO) to enhance both semantic understanding and visual quality.
- A precisão do resultado depende do fornecimento de instruções detalhadas e claras.
- O processamento em lote de alto volume requer alocações de créditos superiores.
What is GLM-Image?
What types of image generation tasks does GLM-Image support?
How does GLM-Image achieve precise text rendering?
Categorias Principais
Tópicos Relacionados
Escrever uma Avaliação
Feedback da Comunidade (0)
Pronto para experimentar GLM-Image?
AI Clothes Swap
AI Clothes Swap is a free AI clothes changer and virtual try-on studio for stylists, e-commerce, and social creators.
Wondershare Relumi
AI photo editor for iOS/Android, fixing blinks, restoring old photos, animating portraits, and enhancing images with text-to-edit features.
FLUX 3
FLUX 3 is a multimodal foundation model for video, image, and audio generation, offering action prediction and real-world visual intelligence.
iLikeIMG
iLikeIMG offers 90+ free AI tools online for photo and video editing, enhancement, and generation without installation.
ImageGenerator IO
ImageGenerator IO is a free AI image generator that creates stunning visuals from text prompts and reference images for various creative projects.
Senzia
Senzia is a free online AI video, image, and audio generator that transforms ideas, text, photos, or audio into cinema-grade visuals without editing skills.
Qwen3.8-Max
Qwen is a family of generalist AI models, including LLMs and multimodal capabilities, developed by the Qwen Team.
Beatmo
Beatmo is an AI tool that transforms still photos into dynamic motion videos, offering photo animation, text-to-visual generation, and image reshaping for creators.